288GB of HBM3e per GPU, 50% more than B200, and 1.5× the dense FP4 compute. Designed for trillion-parameter MoE models, long-context reasoning and agentic inference workloads that are memory-bound before they are compute-bound.
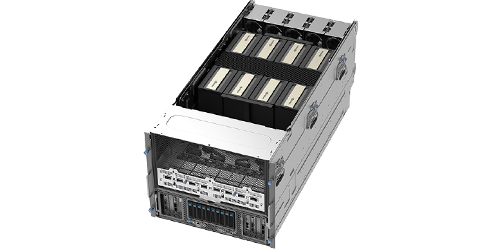
B300 is not a new architecture — it is Blackwell Ultra, a memory and precision refinement of B200 aimed squarely at inference workloads where capacity and KV cache matter more than raw training FLOPS.
Twelve-high HBM3e stacks deliver 50% more memory than B200 and 2× H200. A single B300 can hold a full 70B-parameter model in FP16 plus a substantial KV cache.
15 PFLOPS of dense FP4 compute — a 66% uplift over B200's 9 PFLOPS. FP8 and BF16 remain at B200 levels, so mixed-precision pipelines see immediate FP4 gains.
Larger KV working sets stay resident on-device. 800 Gbps ConnectX-8 scale-out per chip enables disaggregated prefill/decode and wide expert parallelism for MoE serving.
B300's advantage is concentrated in inference and memory-bound workloads. Training throughput per GPU is close to B200, but the larger memory pool changes what fits — and what stays fast.
B300 achieves its memory capacity through 12-high HBM3e stacks — a packaging upgrade over B200's 8-high configuration — combined with the same dual-die Blackwell Ultra die.
Each B300 die carries six 12-high HBM3e stacks, for twelve stacks across the package. Each stack holds 24GB, giving 144GB per die and 288GB per GPU. Memory bandwidth remains 8 TB/s — the same as B200 — but the larger pool means more KV cache stays resident on-device.
For inference workloads, this is the difference between serving a model entirely from GPU memory and spilling KV cache to host RAM. B300 keeps more of the working set on the die, which reduces latency variability and sustains higher throughput as context windows grow.
B300's FP4 uplift and memory capacity target the bottleneck in production AI: inference throughput at long context, under agentic workloads.
Fifth-generation Ultra Tensor Cores with native NVFP4 support deliver 15 PFLOPS dense FP4. Lower precision reduces memory footprint ~1.8× versus FP8 with nearly equivalent accuracy.
Automatic precision switching across FP4, FP6 and FP8 within a single forward pass. The engine picks the lowest precision that preserves accuracy for each layer.
ConnectX-8 doubles scale-out networking to 800 Gbps per chip. This matters for disaggregated prefill/decode and wide expert parallelism in MoE serving.
Every B300 SXM6 node in our fleet is configured with the latest drivers, CUDA toolkit, NVLink 5 fabric and liquid cooling.
| Parameter | B300 SXM | B200 SXM (reference) |
|---|---|---|
| GPU Memory | 288GB HBM3e | 192GB HBM3e |
| Memory Bandwidth | 8 TB/s | 8 TB/s |
| HBM Stack Height | 12-high | 8-high |
| FP4 Tensor Core (dense) | 15 PFLOPS | 9 PFLOPS |
| FP8 Tensor Core (dense) | 7 PFLOPS | ~4.5 PFLOPS |
| FP16/BF16 Tensor Core (dense) | 3.5 PFLOPS | 2.25 PFLOPS |
| FP64 Tensor Core | ~37 TFLOPS | ~37 TFLOPS |
| Streaming Multiprocessors | 160 SMs | 160 SMs |
| CUDA Cores | 20,480+ | ~20,480 |
| GPU Interconnect | NVLink 5 · 1.8 TB/s | NVLink 5 · 1.8 TB/s |
| Scale-Out Networking | ConnectX-8 · 800 Gbps | ConnectX-7 · 400 Gbps |
| PCIe Interface | PCIe Gen6 ×16 | PCIe Gen5 ×16 |
| Form Factor | SXM6 (HGX) | SXM6 (HGX) |
| Process Node | TSMC 4NP · dual-die | TSMC 4NP · dual-die |
| Transistors | 208 billion (2 × 10⁴B) | 208 billion (2 × 10⁴B) |
| TDP | 1,400W · liquid cooling | 1,000W · liquid cooling |
| Usable Memory | 268GB HBM3e | ~180GB HBM3e |
| 8-GPU Node Memory | 2,144GB | ~1,440GB |
The combination of 288GB HBM3e, native FP4 and 800 Gbps scale-out makes B300 the right GPU for memory-bound inference and frontier-scale serving.
Long-context reasoning agents that hold large KV working sets on-device. B300's 288GB keeps more of the agent's state resident, reducing preemption and latency spikes.
Serve mixture-of-experts models with expert parallelism across GPUs. 800 Gbps ConnectX-8 makes all-to-all expert routing practical at rack scale.
Retrieval-augmented generation with large document corpora. A single B300 fits a 70B model in FP16 plus a substantial KV cache for concurrent requests.
Train trillion-parameter models with 8 TB/s memory bandwidth and FP4 mixed precision. The 2,144GB pooled memory per node reduces model parallelism complexity.
Memory-bound HPC workloads — molecular dynamics, climate modelling, CFD — benefit from the larger memory pool and 8 TB/s bandwidth without changing the code.
Deploy B300 clusters with zero-retention, EU or US data residency, DPA / NDA, and SOC 2 / HIPAA-ready infrastructure for regulated industries.
Choose the node size that fits your workload. All configurations include liquid cooling, full root access, NVLink 5 and Quantum-2 InfiniBand fabric.
Tell us about your workload and we will respond within one business day.
Thank you for reaching out to AI Weave Holding. A human engineer will review your request and get back to you within one business day.