141GB of HBM3e memory at 4.8 TB/s — nearly double the capacity of H100 with 1.4× more memory bandwidth. Powered by AI Weave Holding's Quantum-2 InfiniBand cluster for scale-out AI training and inference.
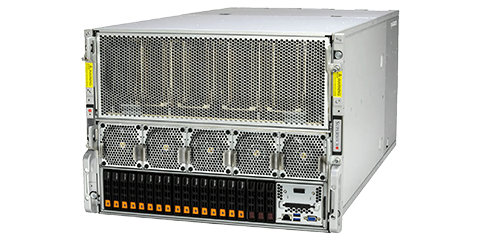
The H200 is the first GPU with HBM3e memory — combining larger capacity, faster bandwidth and the same power profile as H100.
141GB of HBM3e per GPU — nearly double the 80GB of H100. Fits larger models in a single GPU, reduces the need for tensor parallelism across nodes.
4.8 TB/s of memory bandwidth — 1.4× more than H100. Faster KV cache access for long-context inference and memory-intensive HPC simulations.
Up to 1.9× faster LLM inference than H100 on Llama2 70B. Up to 2× faster on GPT-3 175B. Optimized for generative AI and large language models.
Same Hopper compute, larger and faster memory. The result is measurable inference and HPC speedup without changing the power envelope.
Every H200 node in our fleet is connected over NVIDIA Quantum-2 InfiniBand — purpose-built for multi-node AI training and HPC workloads at scale.
Quantum-2 InfiniBand delivers 400 Gbps per port with hardware-level congestion control, adaptive routing and in-network computing (SHARP). The result: near-linear scaling across hundreds of GPUs for distributed training.
Every H200 SXM node in our fleet is configured with the latest drivers, CUDA toolkit and Quantum-2 InfiniBand fabric.
| Parameter | H200 SXM | H100 SXM (reference) |
|---|---|---|
| GPU Memory | 141GB HBM3e | 80GB HBM3 |
| Memory Bandwidth | 4.8 TB/s | 3.35 TB/s |
| FP8 Tensor Core | 3,958 TFLOPS | 3,958 TFLOPS |
| FP16 Tensor Core | 1,979 TFLOPS | 1,979 TFLOPS |
| FP64 | 34 TFLOPS | 34 TFLOPS |
| FP64 Tensor Core | 67 TFLOPS | 67 TFLOPS |
| GPU Interconnect | NVLink 4 · 900 GB/s | NVLink 4 · 900 GB/s |
| PCIe Interface | PCIe Gen5 ×16 | PCIe Gen5 ×16 |
| Form Factor | SXM5 (HGX) | SXM5 (HGX) |
| TDP | 700W | 700W |
| LLM Inference Speedup | Up to 1.9× vs H100 | 1.0× (baseline) |
| HPC Speedup | Up to 1.6× vs H100 | 1.0× (baseline) |
The combination of 141GB HBM3e and 4.8 TB/s bandwidth makes H200 the right GPU for memory-bound AI and HPC workloads.
Run 70B–405B parameter models with long context windows. The 141GB HBM3e fits larger KV caches, reducing tensor parallelism and communication overhead.
Train and serve diffusion models for image, video and 3D generation. Higher bandwidth accelerates the memory-bound denoising and VAE decoding steps.
Full-parameter and LoRA fine-tuning of frontier models. Larger memory means fewer gradient checkpointing trade-offs and faster training iterations.
Molecular dynamics, CFD, climate modelling and quantum chemistry. Up to 110× faster time-to-result vs CPU and 1.6× faster than H100 on MILC.
High-throughput embedding generation and vector indexing for retrieval-augmented generation pipelines at production scale.
Deploy H200 clusters with zero-retention, EU or US data residency, DPA / NDA, and SOC 2 / HIPAA-ready infrastructure for regulated industries.
Choose the node size that fits your workload. All configurations include full root access, NVLink interconnect and Quantum-2 InfiniBand fabric.
Tell us about your workload and we will respond within one business day.
Thank you for reaching out to AI Weave Holding. A human engineer will review your request and get back to you within one business day.