In Stock
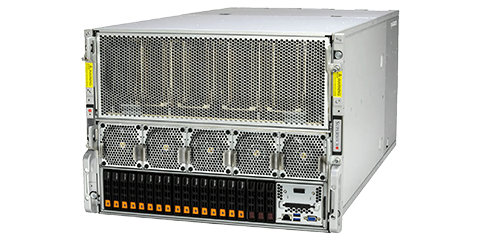
GPU server rental, data agent factory and optimized inference — every product runs on hardware we own and operate. No resellers, no intermediaries, no ambiguity about who is responsible when something breaks. Headquartered in Irvine, California.
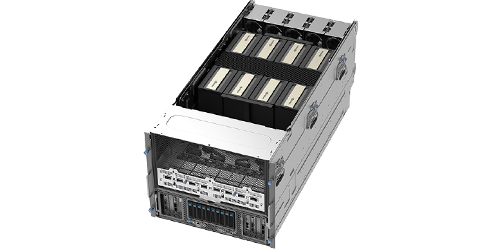
NVIDIA H200, B200 and B300 in stock — not on a six-month waitlist. Every server is single-tenant bare metal with full root access, NVMe storage and Quantum-2 InfiniBand fabric for multi-node training.
Fleets of data agents running on dedicated GPUs to generate, label, distill and verify datasets — from a few thousand samples to millions per day. Built for teams who need high-quality training and evaluation data without building a data pipeline team.
A single OpenAI-compatible endpoint that routes every request to the right workload profile — latency-optimized for agents, throughput-optimized for batch. Running on the same GPU fleet as our rental product, so you can move from prototype to production without changing vendors.
Every GPU node is configurable — choose your CPU, system RAM, storage and network fabric. All configurations include full root access and are deployed with CUDA / ROCm drivers pre-installed.
| Component | H200 Node | B200 Node | B300 Node |
|---|---|---|---|
| GPU count | 1× – 8× H200 SXM | 1× – 8× B200 SXM | 1× – 8× B300 SXM |
| Per-GPU memory | 141GB HBM3e | 192GB HBM3e | 288GB HBM3e |
| System CPU | Dual Intel Xeon 8480+ | Dual Intel Xeon 8592+ | Dual AMD EPYC 9654 |
| System RAM | Up to 3TB DDR5 | Up to 3TB DDR5 | Up to 4TB DDR5 |
| Local NVMe | Up to 8× 3.84TB | Up to 8× 7.68TB | Up to 8× 7.68TB |
| GPU interconnect | NVLink 4 · 900 GB/s | NVLink 5 · 1.8 TB/s | NVLink 5 · 1.8 TB/s |
| Network fabric | 400G IB · 25G RoCE | 400G IB · 25G RoCE | 400G IB · 25G RoCE |
| Root access | Full BIOS + OS | Full BIOS + OS | Full BIOS + OS |
| Drivers | CUDA · ROCm | CUDA · ROCm | CUDA · ROCm |
| Deploy time | 60 min – 3 days | 60 min – 3 days | 60 min – 3 days |
Tell us about your workload and we will respond within one business day.
Thank you for reaching out to AI Weave Holding. A human engineer will review your request and get back to you within one business day.